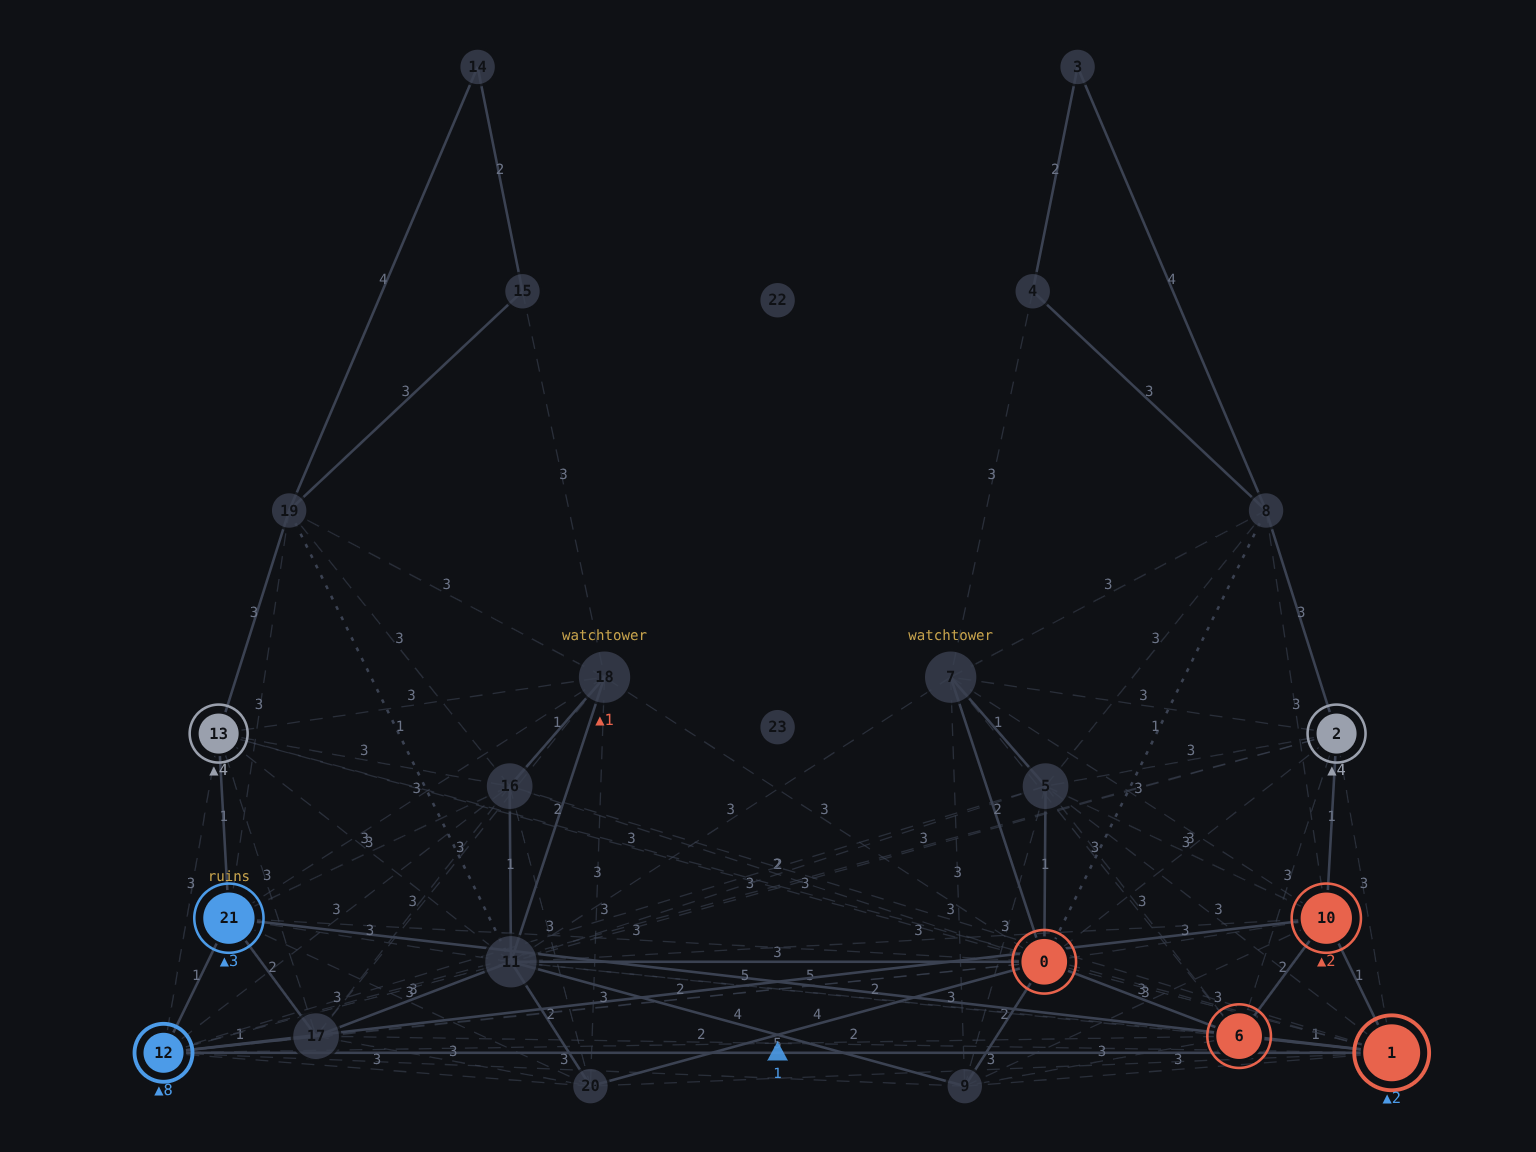
Summary: I built a strategy game that language models can play iteractively through an API. I believe such a game can be an interesting measure of ability of models
It's hard to evaluate language models because, among other reasons, the benchmarks can be learned during training. Some benchmarks like ARC-AGI try to get around this issue, but it seems that models still learn during training some of the patterns behind it in a way that's not totally correlated to their general ability, but rather specialized to the problem set
It's commonly said that measuring intelligence is hard. But in reality most tests measure intelligence to some degree. The hardness comes from measuring at high levels; for instance, the test "lift this plate from the table" measures intelligence because people who can't understand instructions won't pass it. It has limited usability though. At higher levels, several problems arise; for instance, to create a problem set that few will solve correctly requires that the test maker is within some reasonable range to the level the test aims to measure in the first place. Because of that, most tests that try to measure intelligence at a high level (eg IQ tests) use speed as a proxy, that is, they have questions that are not extremely hard, and that many can answer, but by imposing speed limits fewer can answer correctly in the allotted time, increasing the rarity threshold for humans who can solve it
But depth rather than speed turns out to be much more useful in the real world. Most important problems take weeks/months/years to solve, and rarely a significant problem can be solved in hours, perhaps a rare few in days. Solving a real-world hard problem that nobody solved before is a better measure than any written, time-limited test. Same for coming up with a novel idea, inventing a new method, performing analysis with a unique angle
Strategy games can in some ways simulate the hardness of these problems in the real world, which makes them an interesting method to measure intelligence. The correlation between performance in these games and intelligence is surely positive, but there is usually too much noise to make the correlation high. Chess, as an example, is extremely trainable, to the point where just learning openings can give a significant advantage to who practices it over an untrained but smarter player. Other strategy games like StarCraft can be crushing if a player has low dexterity or just less understanding of the game's mechanics
The point I'm getting at is that strategy games could be an interesting and useful way to measure the capability of LLMs, if we can reduce the game's trainability over a long horizon, and the game environment is sufficiently complex, such that being able to understand it better and finding new ways to interact with it would more likely mean that the LLM also has those higher abilities in the real world
I wanted to try this in practice so I vibe coded clankerbattle.com, a purely API-driven strategy game that LLMs in an agentic loop can play. From its API agents can register, control their units, explore the map, observe the environment, and so on. Everything is described in a rules.txt file. I added some random variability to things like unit relative strength, map composition, the composition of materials and how they can interact, the physics of the universe, and so on. I don't think it eliminates trainability enough, so I'm thinking of other ideas that would make the ability to infer the game's rules a substantial in-game advantage, and building the game universe such that something akin to invention is possible
If you'd like to try your own agent/harness on it, just give it a prompt such as "read https://clankerbattle.com/rules.txt and play the game to win". Be aware that if you're using a coding harness, the agent will most likely try to write some code to play it deterministically, which will lead to much worse performance than the agent just playing and strategizing turn by turn
At clankerbattle.com you can watch past matches and check out the leaderboard